Sample Rate
Bit Depth for ASR: How to Choose the Right Bit Depth for Speech Training Data
Explore the intricacies of audio sample rates and their impact on ASR model development. Understand how to choose the right sample rate
 26 September 2023
Sample Rate
Explore the intricacies of audio sample rates and their impact on ASR model development. Understand how to choose the right sample rate
26 September 2023
Author: Jesal Thakkar Founder, FutureBeeAI · Reviewer: Praveen Kumar Co-Founder, FutureBeeAI
Last updated: 12 Nov 2026
A speech team receives 2,000 hours of audio from a vendor. Every file is labeled 16-bit, 16 kHz WAV, exactly as the spec asked. The model trains, but accuracy on real calls stalls well below target. Weeks later, someone opens a few files in an audio editor and finds the problem: much of the audio started life as compressed phone recordings and was simply converted to 16-bit afterward. The label said one thing, and the signal said another. Getting bit depth for ASR right isn't about picking the biggest number. It's about knowing what each bit actually carries, and checking that it's really there.
Why revisit this now? Speech models have moved from clean dictation into call centers, cars, and smart devices, where recording conditions vary wildly. Teams are also buying more data from more sources than ever. That makes audio specs, and the gap between a spec and what's actually inside a file, a much bigger risk than it was when we first wrote this guide in 2023.
When speech is recorded digitally, two numbers decide how faithfully the sound is captured. The first is sample rate, which is how many times per second the signal is measured. We covered that in our guide on sample rate for ASR. The second is bit depth: how many bits are used to store the loudness (amplitude) of each of those samples.
More bits means more possible loudness values. The number of levels is 2 raised to the bit depth:
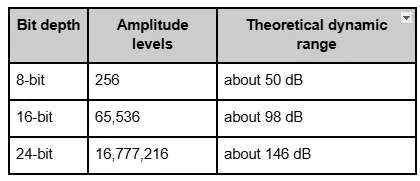
The dynamic range column comes from a standard rule in signal processing: each extra bit adds roughly 6 dB of range, and an ideal converter's signal-to-noise ratio works out to 6.02N + 1.76 dB, where N is the bit depth. Analog Devices' tutorial on converter SNR walks through where that formula comes from.
So what does that range mean for a speech model? To answer that, it helps to see how a sample gets assigned its level in the first place.
An analog-to-digital converter does two jobs. Sampling captures the signal at fixed moments in time. Quantization then rounds the amplitude of each sample to the nearest available level, and that level is stored as a binary number.
That rounding is never perfect. The small difference between the true amplitude and the nearest level is called quantization error, and across a recording it shows up as a faint noise floor. With 2 or 4 bits, the error is obvious: the waveform turns into a staircase and the audio sounds harsh and distorted. At 16 bits, the steps are so fine that the quantization noise sits around 98 dB below the loudest possible signal.
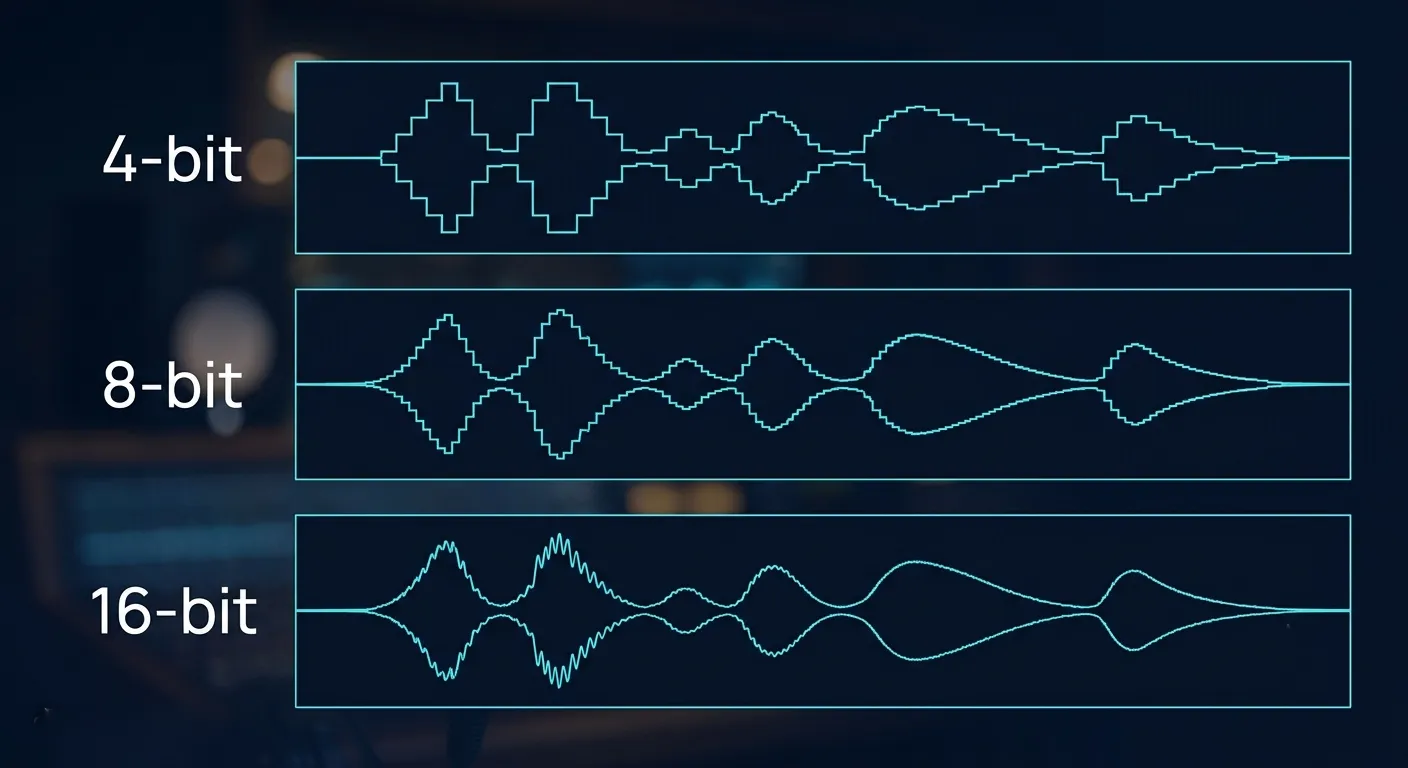
Alt text: Inside How Quantization Turns Sound Into Data
Here's the practical takeaway. Bit depth doesn't decide what words are in the audio. It decides how much quiet detail survives next to the loud parts, and where the noise floor sits. That's why the next question isn't "how many bits?" but "how many bits does speech actually use?"
For most speech recognition work, 16-bit linear PCM is the right answer, and it's the format behind widely used public benchmarks. Google's Speech Commands dataset, for example, is distributed as 16-bit PCM WAV files at 16 kHz.
The reason is simple. Real recordings have a noise floor of their own: room tone, air conditioning, microphone self-noise, traffic outside. In almost every speech recording, that acoustic noise sits far above 16-bit quantization noise. Adding more bits only records the room's noise more precisely. It doesn't add information the model can use to tell one phoneme from another.
Modern ASR models also normalize audio before training. OpenAI's Whisper paper, for instance, describes resampling all audio to 16 kHz and converting it to log-Mel spectrograms. By the time the model sees the data, the file's container format matters far less than what was captured in it.
Then there's cost. At 16 kHz mono, one hour of audio takes about 115 MB at 16-bit, 173 MB at 24-bit, and 230 MB at 32-bit. Across a 10,000-hour corpus, that's roughly 1.2 TB at 16-bit versus 2.3 TB at 32-bit for the same words, plus slower loading and preprocessing on every training run.
If 16-bit is enough, why do so many speech datasets still disappoint? Because the problem is rarely the bit depth on the label.
Most teams check the spec sheet and stop there. The standard practice is to confirm the header says 16-bit, 16 kHz, and move on. But the header only tells you the container. It doesn't tell you how much of those 16 bits the recording really used.
Every 6 dB that a recording sits below full scale costs about one bit of usable resolution. A speaker recorded so quietly that the voice peaks around 30 dB below maximum is effectively using only 11 of the 16 bits. Turn that file up later and you also turn up the noise. Good capture practice, with levels checked at recording time, matters more than any bit depth setting.
The opposite mistake is louder and more damaging. When a speaker shouts or leans into the microphone, peaks above full scale are cut off. That distortion is permanent, and no bit depth can bring it back. Clipped segments teach the model a sound that real users don't make.
This is the trap from our opening example. Converting 8-bit telephony audio or a compressed MP3 to 16-bit WAV produces a valid 16-bit file, but it doesn't restore any detail that was lost. The model still learns from narrowband, compressed speech. If your production audio is the same telephony audio, that might be fine. If it isn't, you've built a mismatch into your training data.
This is also why many teams prefer custom speech data collection, where capture settings are fixed before the first recording. On FutureBeeAI's Yugo platform, sample rate, bit depth, file format, and channel count are set per project, so every contributor records to the same spec on the device itself.
If you're writing a speech data spec and aren't sure which settings fit your use case, talk to our speech data team before collection begins.
So the right bit depth depends less on audio quality in general and more on where your model will be used.
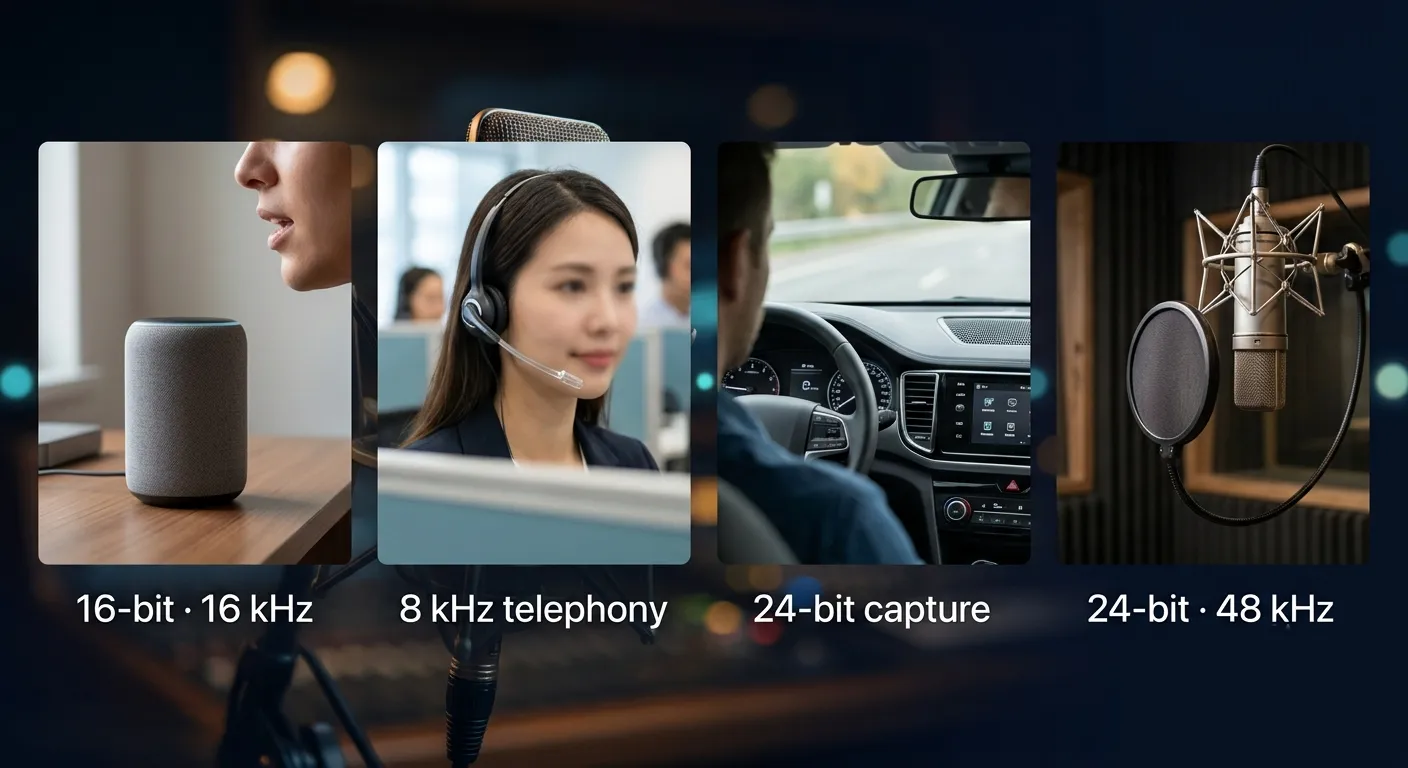
Alt Text: Recommended bit depth and sample rate for ASR, call center, far-field and TTS speech data
The best spec matches your production audio, not the highest number your recorder supports. Here's how that plays out across common speech applications.
1. General ASR and voice assistants: Record and deliver 16-bit PCM WAV, usually at 16 kHz. This covers dictation, voice search, and voice assistant wake words and commands with plenty of headroom.
2. Call center and IVR: Telephone networks commonly carry speech using ITU-T G.711, which encodes 8-bit samples at 8 kHz with logarithmic commanding. Training on real telephony audio at 8 kHz usually beats training on clean wideband audio, because it matches what the model will hear. Our post on call center ASR customization goes deeper on this.
3. Far-field and in-car speech: Levels swing widely in these settings, from quiet speech to sudden loud peaks. Capturing at 24-bit gives extra headroom against clipping, and the files can then be converted to 16-bit with dither for delivery.
4. Text-to-speech: TTS is the exception. The model has to reproduce a voice, not just recognize it, so studio capture at 24-bit and 44.1 or 48 kHz is the common choice.
5. Mixed sources: Whatever you choose, keep it consistent across the dataset. Mixing bit depths, sample rates, and codecs without labeling them makes your evaluation results hard to trust.
Knowing the right spec is half the job. The other half is checking that a dataset actually meets it.
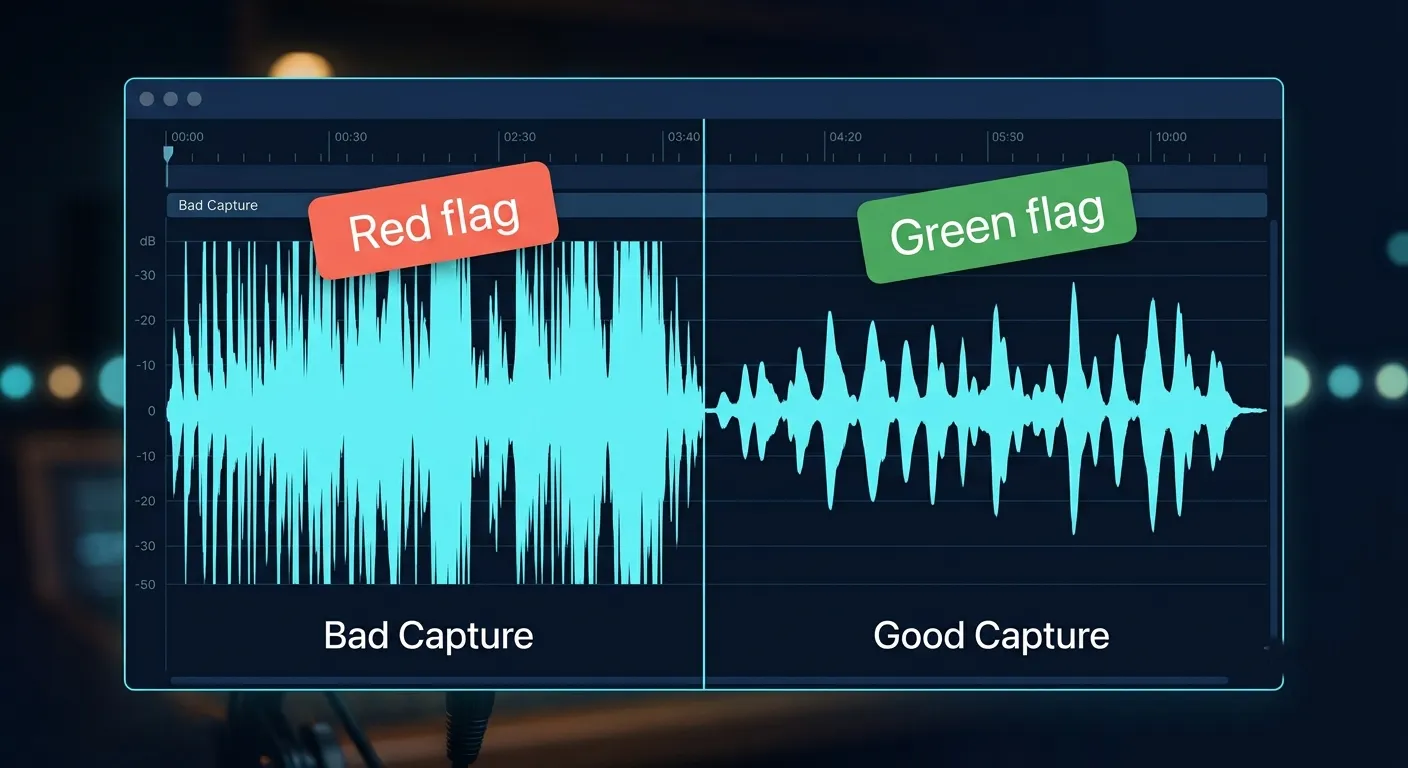
Before you train on any speech data, whether it's off-the-shelf or custom, open a random sample of files and look past the headers.
Red flags
Upconverted audio: Files labeled 16-bit that show the band-limited spectrum and artifacts of telephony or MP3 sources.
Quiet recordings: Peak levels sitting far below full scale, which means the files use only part of their bit depth.
Clipped peaks: Flat-topped waveforms on loud words, which no later processing can repair.
Inconsistent specs: A mix of bit depths, sample rates, and formats with no metadata explaining why.
Green flags
Native capture spec: Audio recorded at the delivered bit depth and sample rate, not converted afterward.
Level checks at capture: Recording levels verified per session, with clipped takes rejected.
Documented metadata: Device, environment, codec, and capture settings recorded for every file.
Spec matched to production: Telephony data for telephony models, wideband data for wideband models.
These checks take an afternoon. Skipping them can cost a full training cycle.
It's tempting to treat bit depth as a box to tick on a spec sheet. But the teams that get speech data right treat it as a signal of how carefully the audio was captured. A dataset with honest, consistent bit depth usually has honest, consistent everything else: levels, environments, speakers, and transcriptions. A dataset where the bit depth was faked in conversion usually has other shortcuts hiding behind it.
So the better question isn't "is this 16-bit?" It's "was this recorded the way my model will be used?"
If you're planning speech data for an ASR or voice product, talk to the FutureBeeAI team about a capture spec built around your production audio. If you're still exploring, browse FutureBeeAI's library of 2000+ datasets, including speech data across 100+ languages.
A. For most speech recognition projects, 16-bit linear PCM is the best choice. It offers about 98 dB of theoretical dynamic range, which is more than real recording environments use, while keeping storage and processing costs manageable.
A. Usually not for training itself. Acoustic noise in real recordings sits well above 16-bit quantization noise, so 24-bit mostly records noise more precisely. 24-bit is useful at capture time in settings with unpredictable loudness, such as cars or far-field rooms, and for text-to-speech recordings.
A. Sample rate is how many times per second the audio is measured, while bit depth is how precisely each measurement records loudness. Sample rate sets the highest frequency captured, and bit depth sets the dynamic range and noise floor.
A. No. Converting to a higher bit depth creates a larger file but cannot restore detail that was never recorded. If your model will process telephony audio, training on genuine telephony recordings is more useful than upconverting them.
A. Uncompressed PCM WAV is the most common and safest format for ASR training data. Lossy formats such as MP3 discard information that cannot be recovered, even if the files are later converted to WAV.
Acquiring high-quality AI datasets has never been easier!!!
Get in touch with our AI data expert now!

 Share this article on