Written by Praveen Kumar, Co-Founder, FutureBeeAI · Reviewed by Jesal Thakkar, Founder, FutureBeeAI
Last updated: 29/09/2026
Picture this. Your invoice OCR model clears the pilot, the finance team signs off, and the rollout begins across your full supplier base. Within weeks, totals from European vendors come through wrong because they use commas as decimal separators, multi-page landscape invoices lose their line items after page one, and a logistics partner's handwritten charges get skipped entirely. The instinct is to retrain or tune the model, but the model is rarely the problem. The invoice dataset it learned from simply never showed it invoices like these.
This gap matters more now than it did a few years ago. Accounts payable automation is moving from controlled pilots to production across global vendor networks, while tax rules and e-invoicing requirements keep changing what an invoice looks like. Every invoice the model misreads becomes a manual correction that eats into the ROI automation promised.
In our earlier piece on invoice processing with AI, we covered why invoice handling needs AI. This one goes a layer deeper, into the data that decides whether that AI actually works.
What an Invoice Dataset Really Is
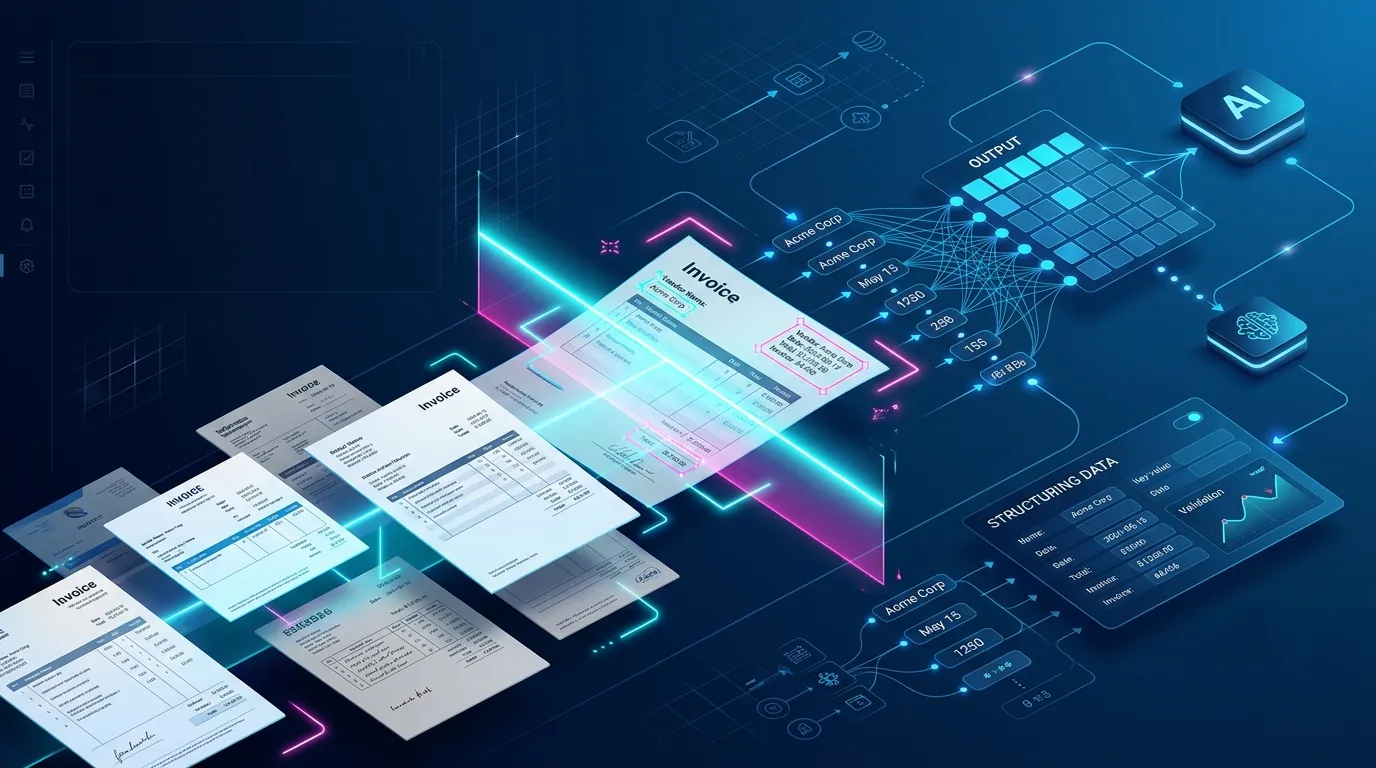
An invoice dataset is an organized collection of invoices built to train and evaluate AI models that read, extract, and process invoice data. The useful version is much more than a folder of PDFs. It has three layers working together: the invoice files, the annotations that mark what matters on each one, and the metadata that describes where each invoice came from.
The annotations do the real teaching. Bounding boxes around fields, key-value pairs linking "Invoice No." to the number beside it, and line-item tables mapped row by row show a model where to look and what each piece of text means, the same principle behind public benchmarks like the ICDAR 2019 SROIE challenge. Metadata such as industry, language, country, and whether an invoice is printed or handwritten lets your team check coverage and trace errors back to the kind of invoice that caused them. Once you see the dataset as the model's only picture of the real world, it becomes much easier to spot where that picture falls short.
A model is only as capable as the invoices it has seen, and that is where most extraction problems begin. When accuracy drops after launch, teams often go after the architecture, adjust thresholds, or retrain on the same data. That is an expensive misdiagnosis, because the model is doing exactly what it was taught, just in a world smaller than the one it now works in.
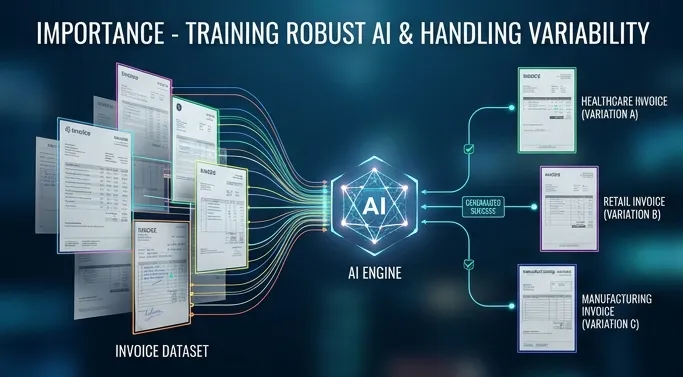
Invoices vary in format, language, structure, and layout far more than most teams expect. Every vendor has its own template, and every region has its own conventions for dates, currencies, and tax. A healthcare invoice lists procedure codes and insurance details, a retailer lists SKUs and discounts, and a manufacturer carries batch numbers and shipping terms, so a model only generalizes across industries when its dataset reflects them.
The common market pattern makes this worse. Many invoice datasets are assembled from a small set of templates and then multiplied, which delivers volume without variety. A model trained this way learns the templates instead of learning what an invoice is. Fixing this starts with choosing the right kind of invoice dataset for the job.
Types of Invoice Datasets and How to Choose
Before you buy or collect anything, get clear on who your model serves: your target users, their industries, and the invoices they actually receive. That tells you which of these dataset types belong in your mix.
1. Industry and Business Type: Invoices in healthcare, retail, and manufacturing differ in format, terminology, and detail, so the first decision is whether you need an industry-specific dataset or a diversified one. The business type adds a second layer. B2C invoices, like an e-commerce order receipt, carry limited consumer fields such as name, contact details, and address, while B2B invoices, like a supplier billing a manufacturer, add bank details, warehouse addresses, hierarchical signature flows, and contract terms.
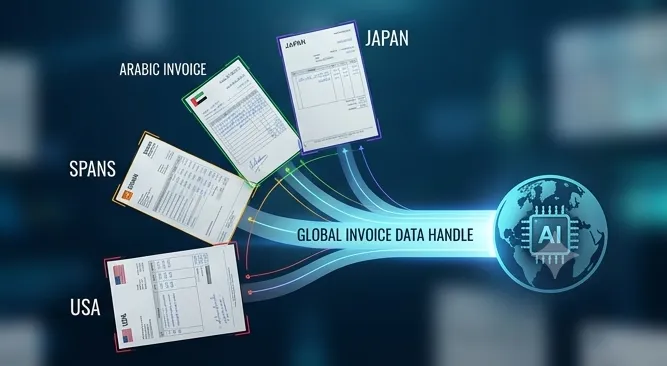
2. Multilingual Invoice Dataset: This comes in two forms. The first is invoices written entirely in different languages, which a model serving a global vendor base needs. The second is mostly English invoices that contain names, addresses, or product details in other languages, which often fits better if your operation mainly handles English invoices from international suppliers.
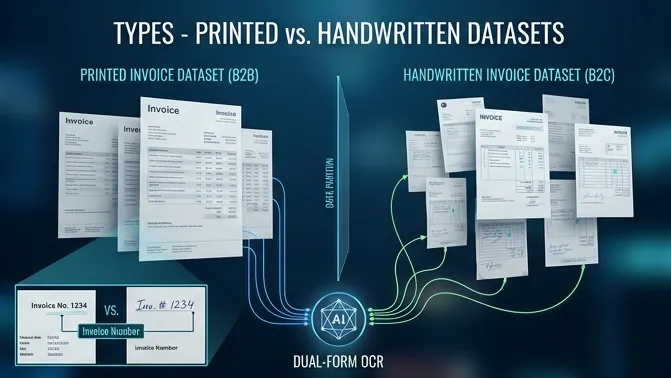
3. Printed vs. Handwritten Invoice Dataset: Printed invoices are mostly B2B, professionally generated, and consistent in layout and font. Handwritten invoices appear more in B2C and small-business contexts, with varied handwriting, ink shades, and personal touches that make extraction harder. Printed invoices usually arrive as PDFs and handwritten ones as scans or raw images, so a model handling both needs both in its training data.
4. Real vs. Synthetic Invoice Dataset: Real invoices expose a model to the diversity it will face after deployment across vendors, locations, formats, and languages. Synthetic invoices are generated to look and behave like real ones, offering controlled variation, rare-scenario simulation, and faster creation on a smaller budget. Synthetic data cannot invent a long tail it has never seen, so the strongest approach uses real data as the foundation and synthetic data to fill specific gaps, balanced against complexity, budget, and timeline.
FutureBeeAI uses a structured blueprint to generate synthetic invoice data that closely mirrors real-world invoices, so synthetic records fill gaps without drifting from reality.
5. Time-Bound Invoice Dataset: Tax structures and business practices change, as India's GST e-invoice system showed when it reshaped B2B invoices, so older invoices can teach patterns that no longer apply. Choosing a base year and including only invoices issued after it keeps the dataset current.
If you are scoping invoice data for a specific region or language mix, explore FutureBeeAI's OCR datasets to see what coverage already exists. Choosing the type is only half the decision, though, because accuracy depends on the variety inside it.
The Diversity Dimensions That Decide Accuracy
Diversity should sit at the top of your checklist when acquiring or collecting an invoice dataset, though how much you need depends on your use case. These dimensions most directly shape how well invoice data extraction holds up in production.
1. Layout and Format: Invoices vary in colors, fonts, headers, footers, and table grids. A well-built dataset works like a practice field where the model meets unusual fonts and creative table layouts before it meets them in a live workflow.
2. Orientation and Page Count: Invoices can be portrait or landscape, and each arranges information differently. Long product lists or extra exhibits such as terms and conditions push invoices onto multiple pages, and a model that has only seen single-page invoices will lose line items that continue across pages.
3. Field-Level Variation: This is where many models quietly fail, because the same field appears in many forms:
Company names: abbreviations, special characters, and legal identifiers such as Pvt. Ltd., LLC, or GmbH
Addresses and contacts: different street formats, city spellings, postal codes, phone formats, and email domains
Invoice numbers and dates: varied numbering styles and date formats such as DD/MM/YYYY, MM/DD/YYYY, and ISO 8601
Product descriptions: free-form text with inconsistent naming
Discounts and taxes: written as percentages, decimals, or words
Totals and bank details: different currencies, number formats, and country-specific account structures
4. Visual and Supporting Elements: Logos add visual complexity, QR codes may need separate processing, and multiple addresses and delivery details reflect the supply chain. Terms, notes, stamps, and signatures add context a model must learn to extract or safely ignore.
This is where geographic reach becomes practical rather than a talking point. FutureBeeAI works with contributors across 100+ languages and 70+ countries, so regional invoice conventions come from the regions that use them. Knowing what variety to look for also makes it much faster to evaluate whether a dataset has it.
How to Evaluate an Invoice Dataset Before You Buy or Build
Off-the-shelf datasets are faster to start with, but they come with a fixed collection and QA history you cannot change. Custom collection takes longer, yet lets you design coverage, annotation rules, and quality checks around your own vendors, regions, and compliance needs. Either way, these signals tell you what you are really getting.
Red flags:
Template multiplication: thousands of invoices that trace back to a handful of layouts
Vague annotation QA: no clear answer on how labels are reviewed
Unclear sourcing: no answer on where real invoices came from or whether contributors consented
Unmasked sensitive data: exposed bank details or tax IDs, a GDPR and privacy risk the moment data enters your pipeline
Green flags:
Documented coverage: clear breakdowns by industry, language, country, format, and time range
Multi-stage QA: human review built into annotation, not only a final spot check
Consent-based sourcing: contributors who know how their documents are used produce cleaner, more consistent submissions, so ethical sourcing is also a quality signal
Single accountability: one team owning collection, annotation, QA, and delivery
That last point matters because every handoff between vendors is a place where quality standards drift. FutureBeeAI handles the full pipeline from collection to delivery and offers 2000+ ready-to-use datasets for teams that need to start faster. All of this comes back to one idea.
The Dataset Is the Model's Worldview
It is tempting to treat the invoice dataset as something you source once on the way to the real work of modeling. In practice, the model can only read the invoices its dataset has shown it, so every gap in coverage becomes a gap in production accuracy that retraining on the same data will never close. Building the invoice dataset is building the model, and teams that treat it that way are the ones whose automation holds up when a new supplier, region, or tax rule arrives.
If you are scoping an invoice extraction pipeline, talk to the FutureBeeAI team to map the right mix of real, synthetic, and custom data. If you are still exploring requirements, browse FutureBeeAI's OCR datasets to see what ready-to-use invoice coverage looks like.
FAQs
Q. What is an invoice dataset used for?
A. It is used to train and test OCR and document AI models that extract fields such as vendor names, invoice numbers, dates, line items, taxes, and totals across different invoice layouts.
Q. How many invoices do you need to train an OCR model?
A. There is no fixed number, because variety matters more than volume. A smaller dataset covering many layouts, languages, and formats usually outperforms a larger one built from repeated templates.
Q. Is a synthetic invoice dataset good enough on its own?
A. Rarely. Synthetic invoices help with controlled variation and rare scenarios, but they cannot fully reproduce real-world unpredictability, so most teams pair them with real data.
Q. Should an invoice dataset include handwritten invoices?
A. Yes, if your model will receive them. A model trained only on printed PDFs will miss or misread handwritten invoices, which are common in B2C and small-business contexts.
 30 January 2024

 Share this article on