Author: Praveen Kumar Co-Founder, FutureBeeAI ·
Reviewer: Jesal Thakkar Founder, FutureBeeAI
Last updated: 23/10/26
A bank's AI team wants a support assistant that sounds like its best agents. They export 40,000 resolved tickets from their helpdesk, clean out the personal data, and fine-tune an open-weight model over a weekend. The result is fluent and fast. It's also curt, quotes a fee policy that changed last year, and confidently answers questions the original agents would have escalated. The model learned exactly what it was shown. The problem was what it was shown. That's the real story of supervised fine-tuning for large language models: the training step is the easy part, and the data decides everything the model does afterward.
The timing makes this more important, not less. Fine-tuning used to need a research team and a large GPU budget. Now a single engineer can adapt a capable model in an afternoon. When the training step stops being the bottleneck, the quality of your demonstration data becomes the only thing that separates your model from everyone else's.
What supervised fine-tuning for large language models actually does
A pre-trained model has read an enormous amount of text and learned to predict the next token. It knows a great deal, but it doesn't know how to be useful. Ask it a question and it might continue with three more questions, because that's a plausible continuation. (Our explainer on what a language model is covers this in more detail.)
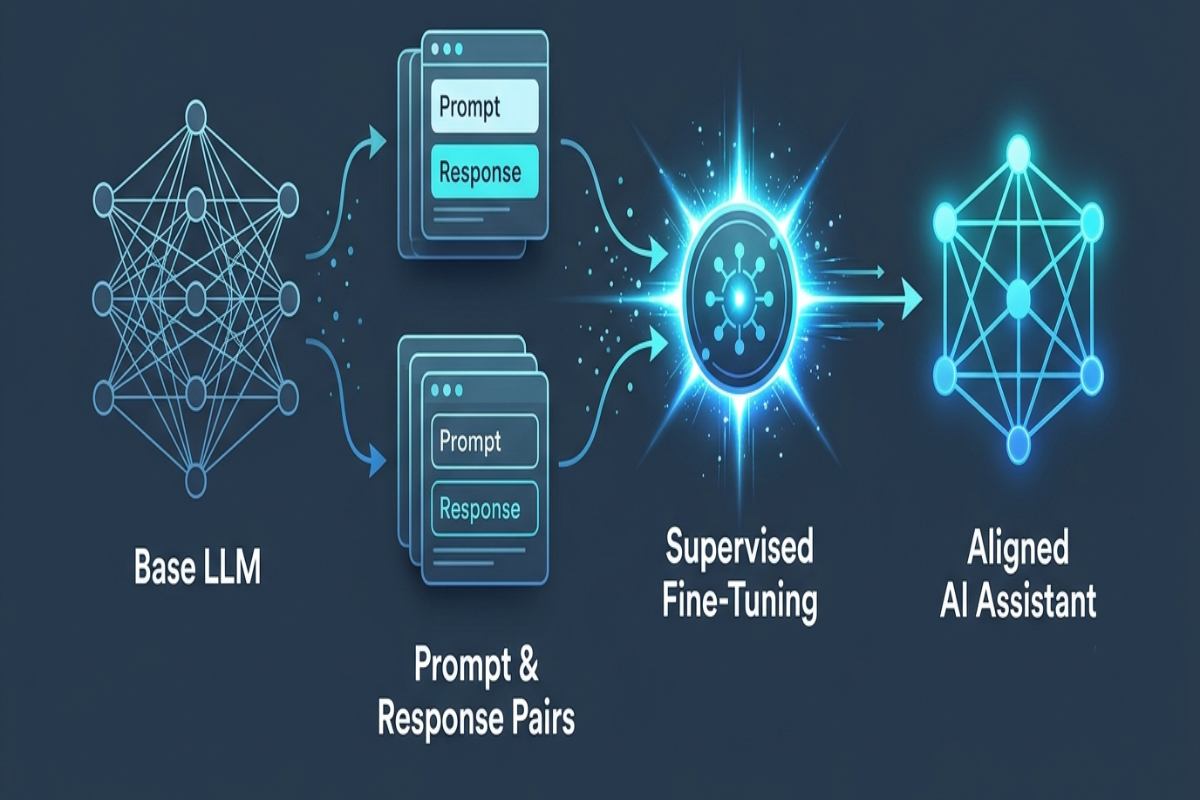
Supervised fine-tuning, or SFT, fixes that by training the model on demonstration data: prompts paired with high-quality responses written by people. The training objective is the same next-token prediction used in pre-training. What changes is the data. Instead of raw web text, the model sees thousands of examples of exactly how a helpful answer should look, and it learns to produce answers in that shape. The three-stage approach of pre-training, then SFT, then learning from human feedback was set out in research like Learning to Summarize from Human Feedback and became the common recipe after InstructGPT. We walk through all three stages in how LLMs are built.
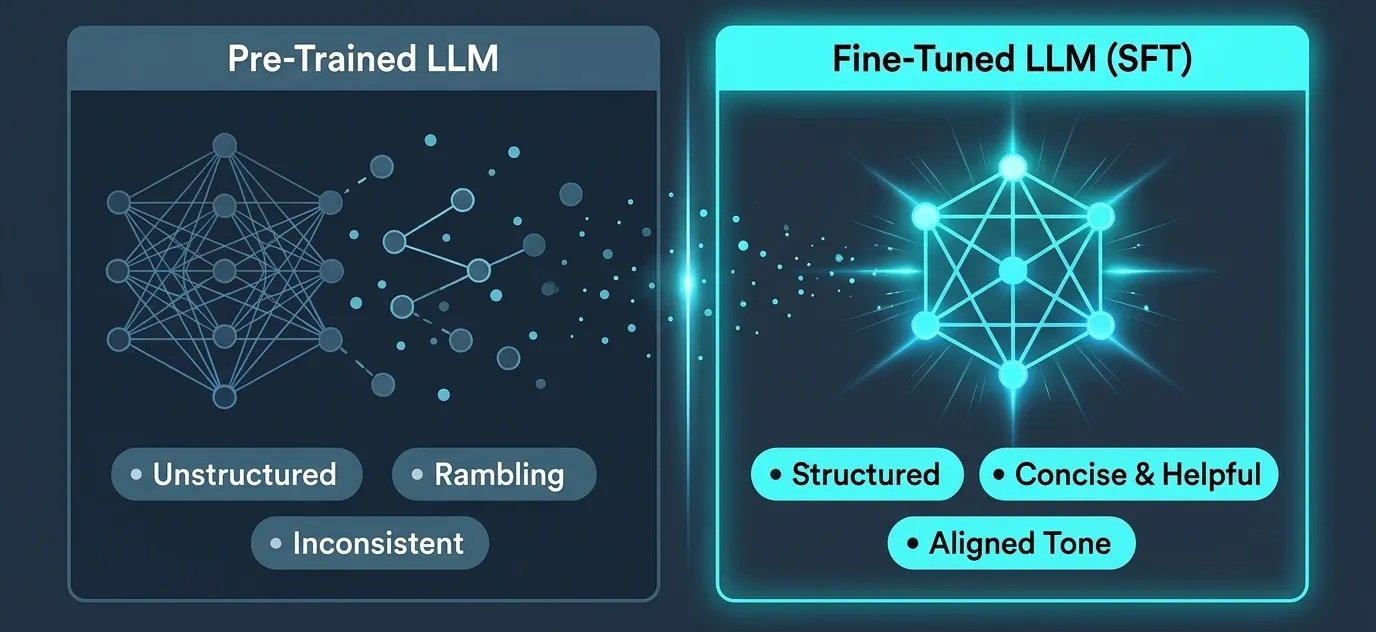
Pre-trained versus fine-tuned LLM response to the same prompt, showing how supervised fine-tuning changes model behavior
Here's the part that's easy to miss. SFT mostly teaches behavior, not knowledge. It shapes format, tone, length, when to ask a clarifying question, and when to decline. It's how a model learns to be helpful, honest, and harmless, the "HHH" goals most alignment work aims for. But a 2024 study on fine-tuning and new knowledge found that models learn unfamiliar facts from fine-tuning slowly, and that as they do, their tendency to hallucinate rises. In other words, if you use SFT to cram in facts the base model never learned, you may be teaching it to make things up with confidence.
So if SFT is mainly about behavior, why has it become such a pressing data problem?
Why SFT got cheap to run but not cheaper to get right
Two shifts changed the economics. First, strong open-weight base models are now widely available, so most teams fine-tune instead of pre-training. Second, parameter-efficient methods made the training step light. LoRA, one of the most widely used approaches, can cut the number of trainable parameters by up to 10,000 times and reduce GPU memory needs by about three times compared with full fine-tuning of a model the size of GPT-3.
What didn't get cheaper is the data. Good demonstration data still needs people who understand the domain, the language, and the standard you're aiming for. And it doesn't take as much of it as teams expect. InstructGPT's supervised fine-tuning set used roughly 13,000 training prompts. The AlpaGasus study went further: filtering a 52,000-example instruction dataset down to its best 9,000 examples produced a better model that trained 5.7 times faster.
The lesson is simple. Your budget for SFT should shift from compute to curation. Yet that isn't how most teams plan it.
Where common thinking about supervised fine-tuning for large language models fails
The first assumption is that more data is better. It usually isn't. A few thousand excellent, varied examples will outperform a large pile of uneven ones, because the model copies the average quality of what it sees. Every weak example pulls the average down.
The second is that your existing logs are ready-made demonstration data. Support tickets, chat transcripts, and internal documents feel like a gift, but they carry everything you don't want: rushed answers, outdated policy, inconsistent tone, and agents who were having a bad day. As our opening example showed, the model learns all of it. Logs are a great source of realistic prompts. They're rarely a good source of ideal responses.
The third is that SFT is the right way to add knowledge. As the hallucination research above suggests, it's a risky way to teach facts. If your assistant needs current policy, pricing, or product details, retrieval from a maintained knowledge base usually does that job better. Use SFT to teach the model how to use that information well.
The fourth is that responses generated by a larger model are good enough. Synthetic responses are fast to produce and can help with coverage, but a dataset built only this way inherits the teacher model's style, blind spots, and mistakes, and it rarely captures how real experts in your domain or your users' language actually talk.
The fifth is that fine-tuning is a one-time job. Models change as you retrain them, and new training can erode earlier skills. An empirical study of continual fine-tuning found catastrophic forgetting across models from 1 to 7 billion parameters. Without a fixed evaluation set, you won't notice what the model lost.
All of which leads to the real question: what does a strong SFT dataset actually contain?
What a strong SFT demonstration dataset covers
Think of an SFT dataset as a written specification of how your model should behave, expressed through examples. It needs to cover the range of things users will ask, in the ways they'll ask them.
Task diversity
A model only gets good at the kinds of tasks it has seen demonstrated. Most general-purpose SFT datasets cover a mix like this:
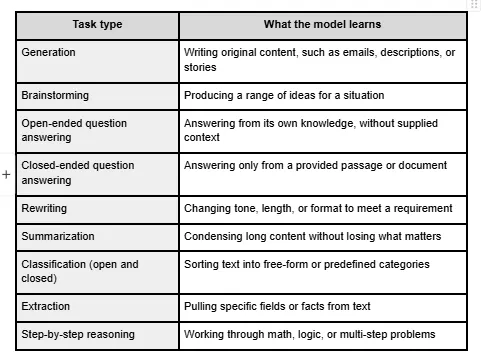
A domain assistant usually leans heavily on a few of these, such as closed-ended question answering and extraction for a policy bot, but it still needs some examples of the rest so it doesn't break when a user asks something unexpected.
Prompt realism
Real users don't write tidy prompts. Your dataset should include instructive prompts, continuation prompts, and prompts with examples in them (in-context learning). Vary the length, from a few words to several hundred. And add the details real requests carry: background context, constraints ("keep it under 100 words"), and persona instructions ("answer as a customer service agent for a telecom provider"). Our piece on prompt and completion goes deeper on how prompts are structured.
Response standards
Responses are where your standards live. Decide in advance how long answers should be, when to use lists, how to cite sources, when to ask a clarifying question, and how to decline politely. If ten writers each follow their own idea of a good answer, your model learns ten conflicting styles.
Language and domain coverage
If your users speak Hindi, Arabic, or Tamil, your demonstration data should be written by native speakers in those languages, not translated from English. Translated responses teach the model to sound translated. The same applies to domains: a clinical answer should be written by someone with clinical knowledge.
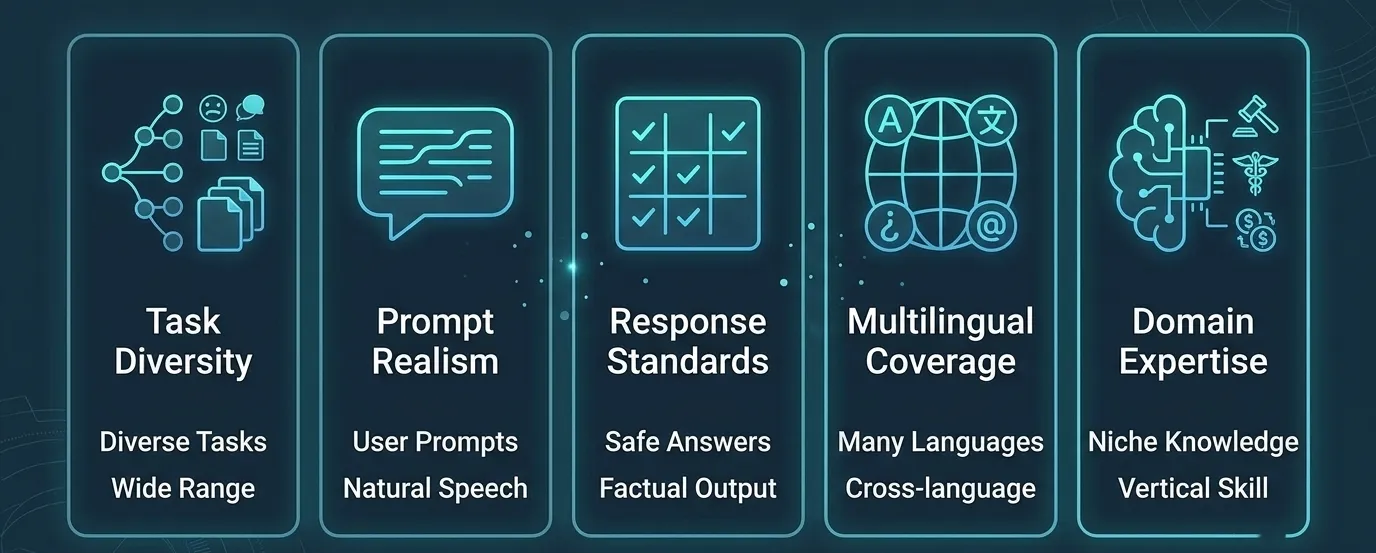
SFT dataset coverage map showing task diversity, prompt types and lengths, response standards, languages, and domains for supervised fine-tuning
FutureBeeAI builds prompt and response data this way, with contributors matched to the domain and language of each project. If you want to see what that looks like in practice, browse our chat prompt and response datasets before you scope a custom set.
Knowing what to cover is half the work. The other half is a process that keeps quality consistent across thousands of examples.
How to build an SFT dataset, step by step
Teams that get reliable results from SFT tend to follow the same sequence.
1. Define the behaviors and build an evaluation set first: Write down what the model must do well, what it must refuse, and how it should sound. Then build a held-out set of test prompts so you can measure progress and catch regressions after every training run.
2. Write guidelines before anyone writes a response: Cover format, length, tone, citation rules, refusal behavior, and ethics. Include good and bad examples. Vague guidelines are the most common cause of inconsistent data.
3. Match contributors to the domain and language: Recruit people who know the subject and speak the language natively. A community of vetted experts is far easier to calibrate than an anonymous crowd paid by volume.
4. Run a pilot and calibrate: Produce a small batch, review it against the guidelines, and align writers on edge cases before full production starts.
5. Produce in batches with layered QA: Tag each pair with task type, prompt type, length, and domain so you can check coverage. Review first internally, then with your AI team, and feed corrections back into the guidelines.
6. Train, evaluate, and iterate: Fine-tune, test against your evaluation set, and look at where the model falls short. Then add targeted examples for those gaps. Our guide to data evaluation for LLMs covers how to judge outputs consistently.
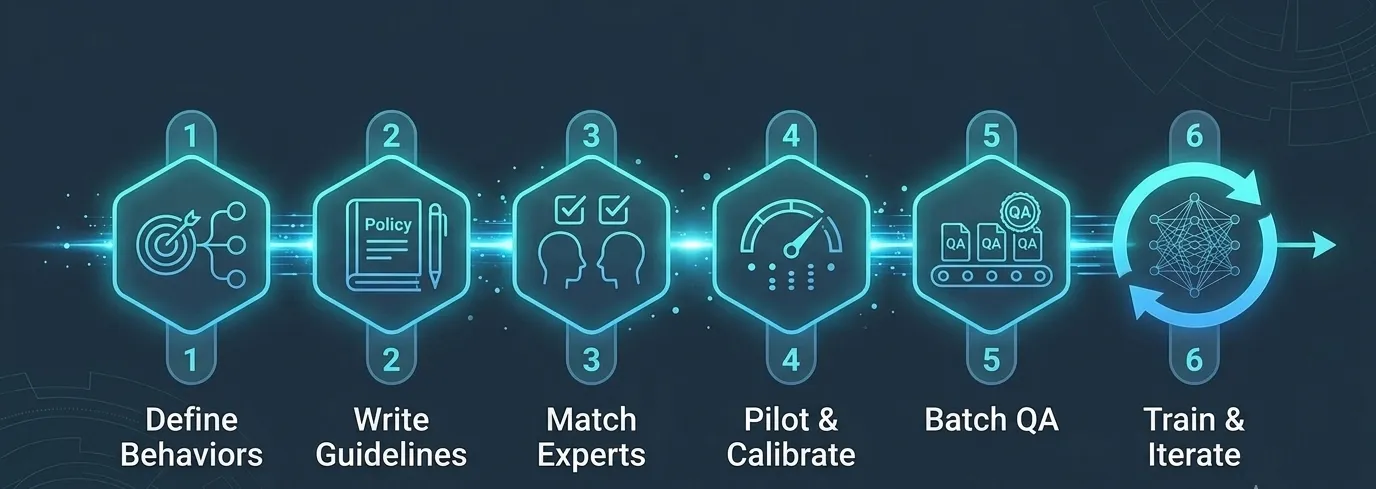
Six-step process for building a supervised fine-tuning dataset, from defining behaviors and evaluation set to training and iterating
Whether you build in-house or work with a partner, a few signals tell you quickly whether the data will hold up.
Red flags and green flags when evaluating SFT data
Red flags:
Priced and promised by row count: The proposal talks about volume but not about coverage, guidelines, or reviewer agreement.
No written guidelines: Writers are told to "write a good answer" and left to interpret it.
Unverified writers: No evidence that contributors have the domain or language expertise the task needs.
Translated instead of native data: Non-English pairs are machine-translated from English.
No consent or provenance trail: Nobody can show where the prompts and responses came from or who agreed to their use.
Green flags:
Coverage stated in numbers: Counts by task type, prompt type, length, domain, and language.
Guidelines you can read: Clear rules for format, tone, refusals, and edge cases, with examples.
Calibration and agreement checks: Pilot rounds and reviewer agreement measured before full production.
Domain and native-language contributors: Writers selected for the subject and language, not just availability.
Documented, consented sourcing: Every pair traceable to a contributor who agreed to its use.
The last point is a quality argument as much as a compliance one. Contributors who are consented, fairly paid, and matched to the work write more careful responses, and data with a clear origin stays usable when your model reaches customers and auditors. That's the principle behind how FutureBeeAI sources human-in-the-loop fine-tuning data across 100+ languages and 70+ countries.
Your fine-tuning data is your model's job description
It's tempting to think of SFT as a training step. In practice, it's the moment your model learns your standards: what a good answer looks like, what it should never say, and how it should sound to your users. The base model is the part you can download. The behavior is the part you have to write down, example by example.
So the useful question isn't "how many examples do we need?" It's "have we shown the model, clearly and consistently, the behavior we expect?" Get that right, and a modest dataset will take you further than a model twice the size.
If you're planning supervised fine-tuning for your model, talk to the FutureBeeAI team about custom prompt and response data collection built around your domain and languages. If you're still exploring, browse our library of 2000+ ready-to-use datasets across text, speech, and multimodal AI.
FAQs
Q. What is supervised fine-tuning for large language models?
A. Supervised fine-tuning (SFT) trains a pre-trained language model on prompts paired with high-quality, human-written responses. It teaches the model how to respond, including format, tone, and instruction following. It's usually the first alignment step after pre-training.
Q. What is the difference between pre-training and supervised fine-tuning?
A. Both use the same next-token prediction objective, but with different data. Pre-training uses huge amounts of raw text so the model learns language and general knowledge. SFT uses a much smaller, curated set of prompt and response pairs so the model learns to behave like a helpful assistant.
Q. How much data do you need for supervised fine-tuning?
A. Usually less than teams expect. InstructGPT used roughly 13,000 training prompts, and research such as AlpaGasus showed that a carefully filtered 9,000-example set beat the original 52,000. Coverage, consistency, and quality matter more than raw size.
Q. Can supervised fine-tuning teach an LLM new facts?
A. It can, but it's risky. Research suggests that models learn new facts from fine-tuning slowly and become more prone to hallucination as they do. For facts that change, such as policies or prices, retrieval from a maintained knowledge base is usually the better approach.
Q. What is the difference between SFT and RLHF?
A. SFT shows the model examples of good answers so it can imitate them. RLHF and related preference methods show the model which of several answers people prefer, so it learns finer judgment. Most teams run SFT first, then add preference training if needed.
 31 October 2023

 Share this article on