Author: Jesal Thakkar Founder, FutureBeeAI · Reviewer: Praveen Kumar Co-Founder, FutureBeeAI
Last updated: 08/10/26
Picture a team that picks a capable open-weight base model, fine-tunes it on a few thousand examples, and ships an internal assistant. The answers sound fluent, but they're wrong often enough that nobody trusts them. So the team tries a bigger model, and the problem doesn't go away. What went wrong is easy to miss: the few thousand examples were written in a hurry by whoever had time that week. If you want to understand how LLMs are built, this is the part most explanations skip. The architecture gets the headlines, but the data at each stage decides how the model actually behaves.
This matters more now than it did two years ago. Strong base models are available to almost everyone, so the base model is no longer what separates one product from another. What separates them is post-training, and post-training is almost entirely a data problem.
Why How LLMs Are Built Is Really a Question About Data
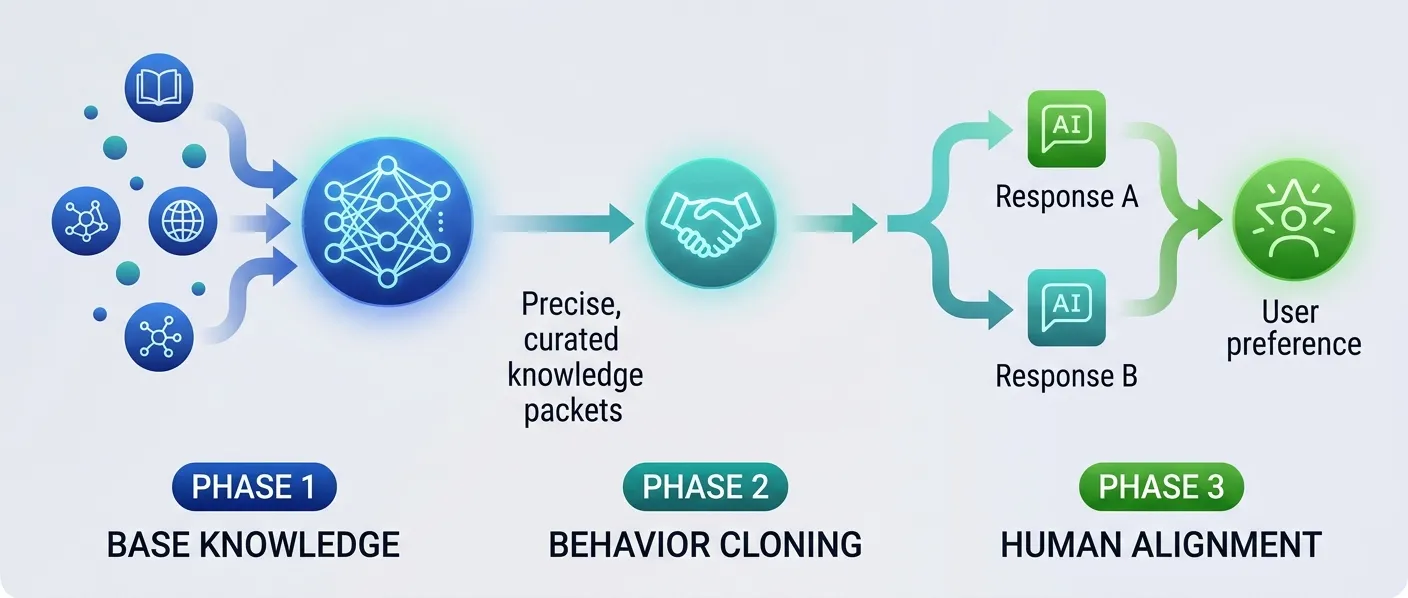
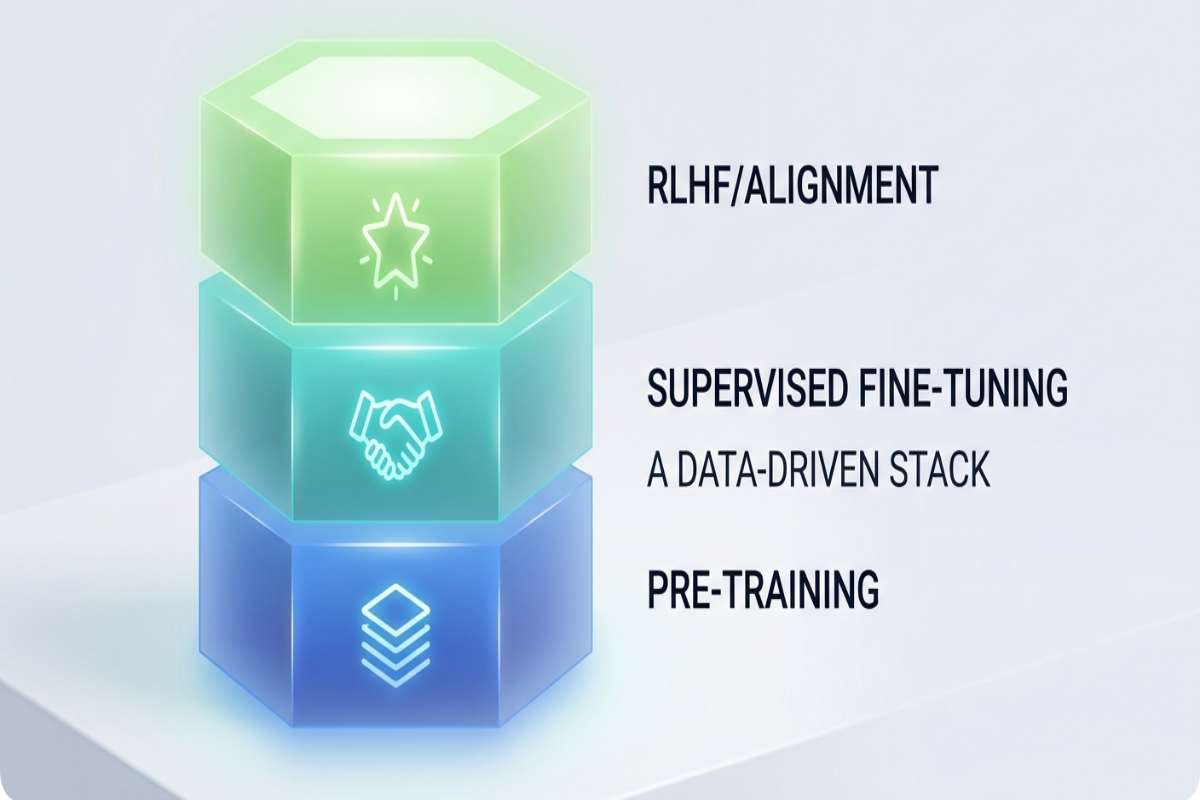
Most modern large language models go through three phases of training: pre-training, supervised fine-tuning (SFT), and reinforcement learning from human feedback (RLHF). The goal across all three is a model that is helpful, honest, and harmless, which researchers often shorten to "HHH."
What's easy to overlook is that each phase asks something different of the data. Pre-training needs scale. Supervised fine-tuning needs precision. RLHF needs consistent human judgment. A team that treats all three as "get more data" ends up with a lot of text and a model that still doesn't do what they need.
To see why the data mattered more than the model in our opening example, you have to look at what each phase of the LLM training process actually asks of it.
Phase 1, Pre-training: Building Knowledge, Not Behavior
Pre-training is where the model learns language itself. It reads a huge body of text and learns one deceptively simple task: predict the next token. Do that across trillions of tokens and the model picks up grammar, facts, reasoning patterns, and a surprising range of skills along the way. This scale-first approach became the standard after research like OpenAI's GPT-3 paper showed how far next-token prediction could go.
Here's a useful way to think about it. Translation, summarization, and classification all look like different tasks, but to a pre-trained model they're all the same thing: completing text. If you write "French: bonjour. English:", the most likely next word is "hello." We explored this idea in more depth in our piece on prompt and completion in LLMs.
The catch is that a base model knows a lot but doesn't know how to help you. Ask it a question and it might continue with three more questions, because that's a statistically plausible completion. Pre-training also sets hard limits for every later phase. If a language, dialect, or domain is thin in the pre-training data, fine-tuning can't fully make up for it later.
A model that knows a lot but can't hold a useful conversation needs to be shown what a good response looks like, and that's the job of the second phase.
Phase 2, Supervised Fine-Tuning: Teaching the Model How to Respond
Supervised fine-tuning trains the base model on demonstration data: prompts paired with high-quality responses written by people. The model learns by imitation, which is why SFT is often described as behavior cloning. It sees what an ideal answer looks like and learns to produce answers in that shape.
It helps to be clear about what SFT does and doesn't do. It mostly teaches format, tone, and how to follow instructions. It adds very little new knowledge. The LIMA study made this point well: a 65-billion-parameter model fine-tuned on only 1,000 carefully curated examples produced responses that held up well against much larger systems in human evaluations. The takeaway for teams is simple. A small set of excellent examples does more than a large set of mediocre ones.
What Separates Good Demonstration Data from Bad
Good demonstration data has a few things in common:
Domain-qualified authors: A clinical answer should be written by someone who understands clinical language, not by a generalist following a template.
Prompt diversity: The prompts should cover the messy, ambiguous, and edge-case questions real users ask, not just the clean ones.
Consistent style: If ten writers each follow their own idea of a "good answer," the model learns ten conflicting styles.
Factual accuracy: The model will copy the confidence of its examples, so any errors in them get copied too.
This is also where how the data is sourced shows up in the quality. Contributors who are consented, paid fairly, and matched to the domain tend to write more careful responses than anonymous workers paid by volume. FutureBeeAI builds human-in-the-loop fine-tuning data on this principle, with contributors selected for the domain and language of each project.
If you're scoping demonstration data for a domain-specific assistant, talk to the FutureBeeAI team about how to design the prompt set before anyone starts writing.
SFT teaches the model what a good answer looks like, but it can't tell the model which of two plausible answers is better. That's where human feedback comes in.
Phase 3, RLHF: Aligning the Model With Human Judgment
Reinforcement learning on its own would be expensive and risky for a language model, because there's no simple score for "good answer." RLHF solves this by teaching the model what humans prefer.
Comparison Data and the Reward Model
The process works in two steps. First, the fine-tuned model generates several responses to the same prompt, and human labelers rank them from best to worst. These rankings become comparison data, also called preference data. Second, a separate reward model is trained on that comparison data so it can predict which responses people would prefer. The SFT model is then tuned to produce responses the reward model scores highly.
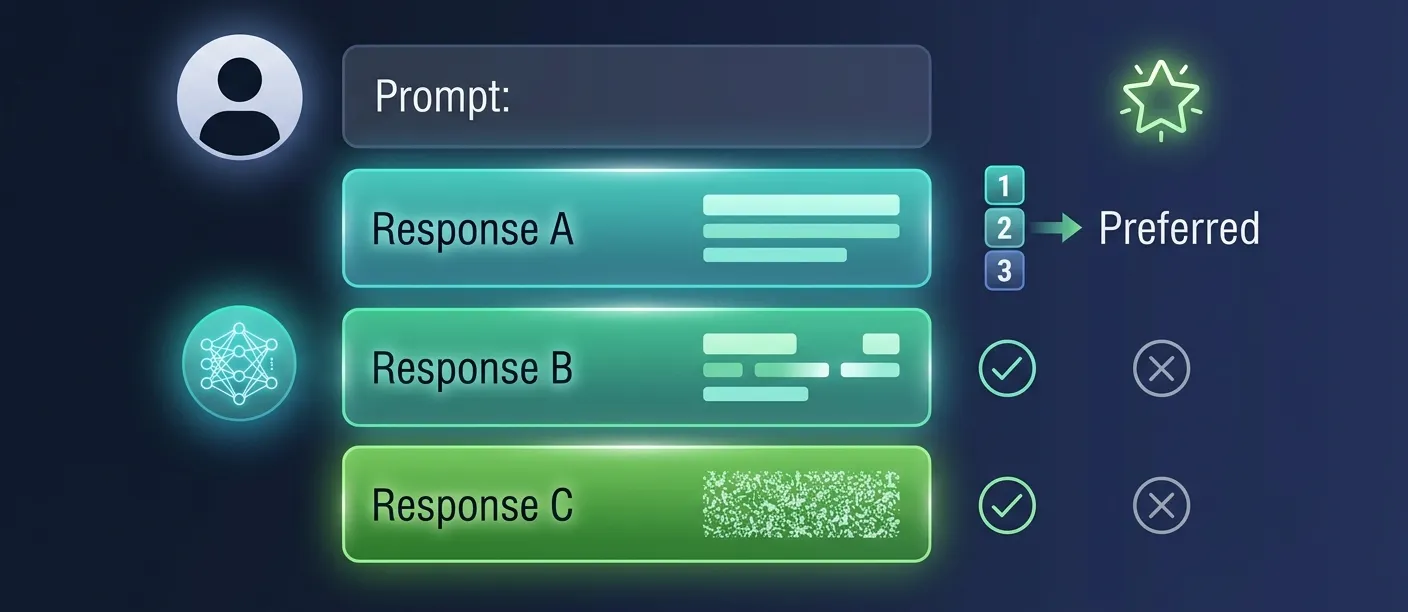
The results can be striking. In OpenAI's InstructGPT research, labelers preferred outputs from a 1.3-billion-parameter model trained with RLHF over outputs from the 175-billion-parameter GPT-3. In other words, the alignment data did more for user preference than a 100x increase in model size.
Beyond Classic RLHF
The field hasn't stood still. Direct Preference Optimization (DPO) skips the separate reward model and trains directly on preference pairs. Approaches like Constitutional AI use AI-generated feedback guided by written principles to reduce how much human labeling is needed. These methods make alignment cheaper and simpler to run. They don't remove the need for good preference data. If the human rankings are noisy, inconsistent, or culturally narrow, the model learns that noise and presents it as a preference.
When an LLM misbehaves in production, though, teams rarely trace the problem back this far.
Where LLM Training Pipelines Actually Break
When a model gives poor answers, the usual response is to swap the base model, tune hyperparameters, or add compute. Sometimes that's the right fix. More often, the root cause sits in the demonstration or preference data, and no amount of model work will fix it. This misdiagnosis is expensive, because each retraining cycle burns weeks of time and budget before anyone looks at the data.
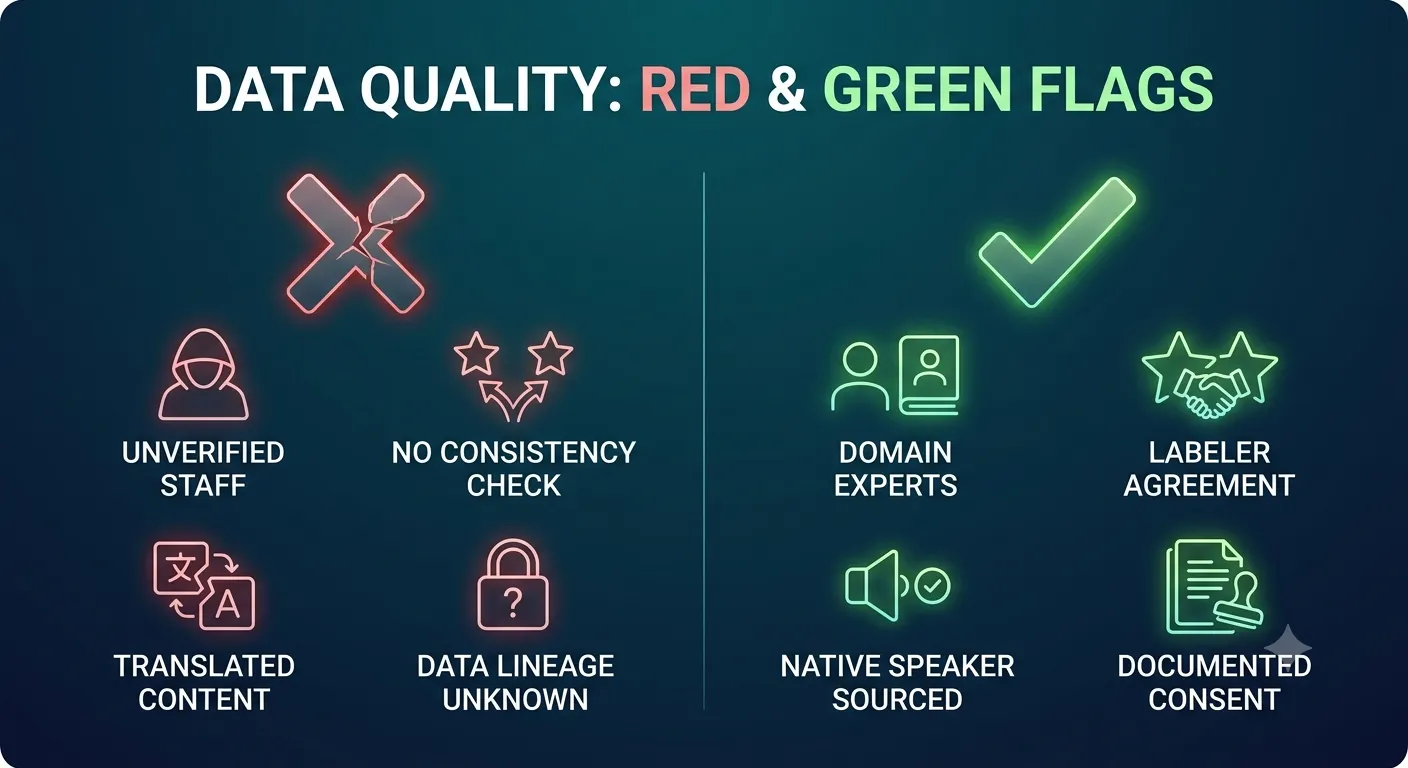
The standard practice in much of the industry makes this worse: annotation work goes to a large anonymous crowd, quality is measured by throughput, and nobody checks whether two labelers would rank the same responses the same way. If you're evaluating your own pipeline or a data partner, here's what to look for.
Red flags:
Unverified annotators: No evidence that contributors have the domain or language expertise the task needs.
No agreement checks: Rankings are collected but never tested for consistency between labelers.
Translated instead of native data: Non-English prompts and responses are machine-translated rather than written by native speakers.
No consent trail: Nobody can tell you where the data came from or whether contributors agreed to its use.
Green flags:
Domain-matched contributors: Writers and raters are selected for the subject matter, not just availability.
Calibration rounds: Labelers align on guidelines with test batches before full production starts.
Documented consent: Every contributor and data point can be traced back to its source.
One accountable owner: Collection, annotation, and quality checks are handled under one standard, without handoffs between vendors.
These failures compound fastest once the model has to work in more than one language.
Why Multilingual LLMs Multiply Every Data Problem
Everything above gets harder when a model needs to work in Hindi, Tamil, Swahili, or Arabic as well as English. Pre-training data for many of these languages is thin, so the model starts with weaker foundations. Demonstration data translated from English teaches the model to sound translated, with the wrong idioms, the wrong level of formality, and examples that don't fit the culture. Even preference data shifts: what counts as a "better" answer can depend on cultural expectations about directness, politeness, and detail.
This is why native-speaker data matters more than any translation workflow can replace. FutureBeeAI works across 100+ languages with contributors in 70+ countries, and that crowd community works as a built-in quality layer. Native speakers catch mistakes that a translation check never would.
All of this changes how teams should plan the data side of building or fine-tuning an LLM.
What This Means for Teams Building or Fine-Tuning LLMs
If you're building on an existing base model, which most teams are, here's the practical shift in thinking:
1. Budget for post-training data like you budget for compute: A few thousand excellent demonstration examples and a well-calibrated preference set will often move your model further than a larger base model.
2. Design data around your domain, not a template: Off-the-shelf instruction sets come with someone else's style and assumptions. Custom data collection lets you shape prompts, response style, and quality checks around your users and your risk tolerance.
3. Check data before retraining: When outputs disappoint, audit a sample of your demonstration and preference data before you change the model.
4. Keep one owner for the pipeline: Every handoff between collection, annotation, and quality review is a place where standards can slip.
So how are LLMs built? The base model is the part you can rent. The behavior, meaning how your model answers, what it refuses, and how it sounds to your users, is the part you have to build, and you build it with data.
If you're scoping SFT or RLHF data for your model, talk to the FutureBeeAI team to map the right approach for your use case. If you're still exploring, browse FutureBeeAI's library of 2000+ ethically sourced datasets across speech, text, and multimodal AI.
FAQs
Q. What are the main stages of building an LLM?
A. Most LLMs are built in three stages. Pre-training teaches the model language from very large text datasets. Supervised fine-tuning teaches it to follow instructions using expert-written examples. RLHF or a related preference method aligns its answers with what people actually find helpful.
Q. What is the difference between SFT and RLHF?
A. SFT shows the model examples of good answers so it can imitate them. RLHF shows the model which of several answers people prefer, so it learns to choose better responses. SFT shapes the format of answers, and RLHF shapes the judgment behind them.
Q. What is demonstration data in LLM training?
A. Demonstration data is a set of prompts paired with high-quality responses written by people, usually domain or language experts. It's used in supervised fine-tuning to teach the model how a helpful answer should look.
Q. How much data do you need to fine-tune an LLM?
A. Less than most teams expect, as long as the quality is high. Research such as the LIMA study showed strong results from about 1,000 carefully curated examples. The right number depends on your domain, the number of languages, and how specialized the behavior needs to be.
Q. Is RLHF still used, or has DPO replaced it?
A. Both are in use. DPO and AI-feedback methods have made alignment simpler and cheaper, but they still depend on good preference data. The method has changed, but the need for consistent, well-sourced human judgment hasn't.
 12 September 2023

 Share this article on