Author: Jesal Thakkar, Founder, FutureBeeAI · Reviewer: Praveen Kumar, Co-Founder, FutureBeeAI ·
Last updated: 06/10/26
Introduction
A driver on the highway outside Pune says "Hey Aria, call home" with the windows down and cricket commentary playing on the radio, and the assistant stays silent. Ten minutes later, a radio ad containing a word that sounds close to "Aria" wakes the same assistant in the middle of a conversation. Neither failure appeared during lab testing, and both trace back to the same root cause: a wake word dataset that never represented the driver, the cabin, or the radio.
The stakes around this problem are rising because the wake word has become a brand asset. Automotive OEMs, appliance makers, and consumer electronics companies increasingly want their own activation phrase rather than a borrowed one, and Juniper Research projected that voice assistant devices in use would reach 8.4 billion by 2024, more than the world's population. Each of those devices runs a small, always-on detection model on low-power hardware, which means the model has very little capacity to compensate for what its training data left out. Whatever the voice assistant speech dataset fails to represent, the device fails to hear.
Why the Wake Word Is the Hardest Two Seconds in Voice AI
Every voice interaction has two parts that are trained and deployed very differently. The wake word (also called a trigger word or hotword) is the short phrase that tells the device to start listening, while the voice command is the instruction that follows it. Put together, "Hey Aria" plus "play my driving playlist" becomes one complete interaction, but the first half is handled by a tiny keyword spotting model running on the device around the clock, and the second half is usually passed to a larger speech recognition and intent pipeline.
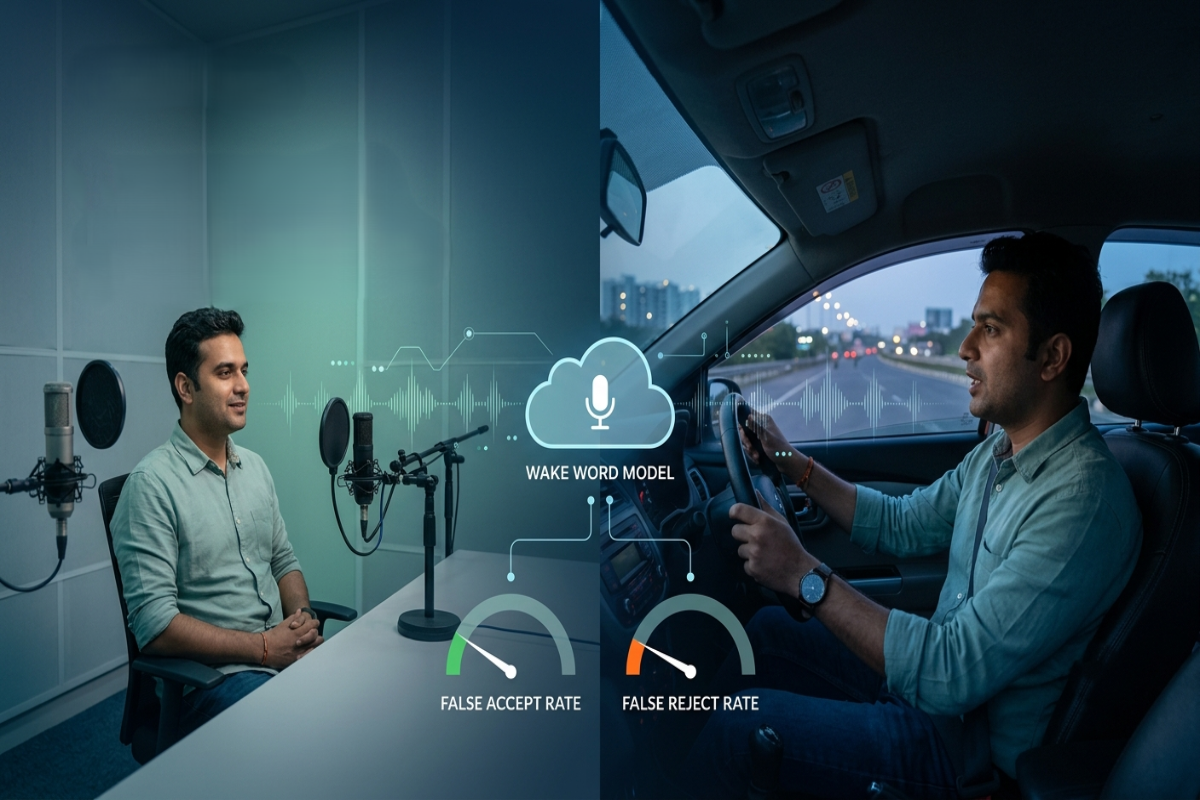
That always-on design is what makes wake word detection so unforgiving. The model has to judge every second of ambient audio, in every room or cabin the product ships into, and it fails in two directions that carry very different costs. A false accept, where the device wakes when nobody called it, erodes trust and raises privacy concerns in a way users remember. A false reject, where the device ignores a real request, quietly trains users to stop speaking to the product at all, which shows up later as low engagement rather than as a bug report.
A custom wake word adds one more constraint that generic speech projects never face: no public recordings of the phrase exist. A brand that invents "Hey Aria" cannot borrow an open corpus or license an off-the-shelf voice command dataset for that exact phrase, because nobody has said it on record yet. Every training sample has to be collected, which means the decisions made during collection determine the model's ceiling before a single experiment is run.
The Hidden Problem: Wake Word Models Fail on What They Never Heard
When a wake word model underperforms in field testing, the first instinct is usually to tune the model. Teams adjust the detection threshold, try a different architecture, add more training epochs, or apply heavier augmentation, and each change moves the false accept and false reject numbers around without fixing either one. The pattern repeats because the problem was never in the model. It was in the coverage of the data.
This misdiagnosis is expensive because it consumes the time that should go into collection. A threshold change that lowers false rejects for one accent group often raises false accepts in noisy environments, so the team ends up trading one failure for another while the release date slips. The real question is not how to make the model more sensitive, but which speakers, acoustic conditions, and confusable sounds the model has simply never encountered.
Coverage gaps also hide well in aggregate metrics. A model can post an acceptable overall false reject rate while failing badly for older speakers, for people who speak fast, or for anyone using the device across a room instead of up close. Those groups are small in the test set, so the average looks fine, but they are real customers in the market, and they are usually the ones who stop using the product first. Understanding what proper coverage looks like is the starting point for fixing this, and it breaks down into four layers.
What a Production-Grade Wake Word Dataset Must Cover
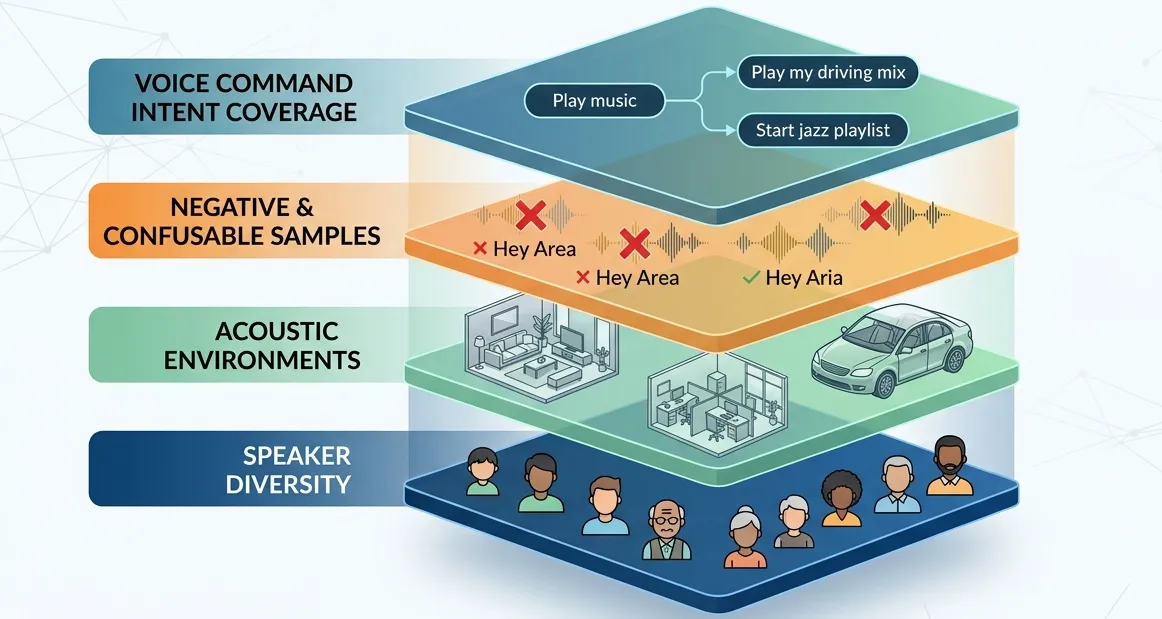
A wake word dataset built for production is designed around the conditions the product will face after launch, not the conditions that are easiest to record. That design work happens across four layers, and a gap in any one of them shows up later as a field failure that looks like a model problem.
Speaker Diversity Across Accent, Age, and Speech Rate
The same two-word phrase sounds very different across a population. Accent shifts vowel quality and stress, age changes pitch and articulation, and speech rate compresses or stretches the phrase in ways a model trained only on careful, mid-tempo speech will not recognize. For multilingual markets the challenge multiplies, because a single wake word is often spoken by people whose first language shapes how they pronounce it. This is where crowd diversity stops being a reporting metric and becomes a quality control layer: FutureBeeAI collects with contributors across 100+ languages and 70+ countries, so speaker balance can be designed into the collection plan instead of patched after the first field test.
Acoustic Environments and Recording Devices
A wake word spoken into a phone held close to the mouth is a different signal from the same phrase spoken across a living room to a smart speaker. Production datasets need both near-field and far-field recordings, along with the environments the product will live in, such as car cabins at highway speed, kitchens with running appliances, and rooms with a television playing. Device coverage matters just as much, since microphone arrays, sample rates, and audio formats vary across hardware, and a model trained on one microphone profile often degrades on another.
Negative and Confusable Samples
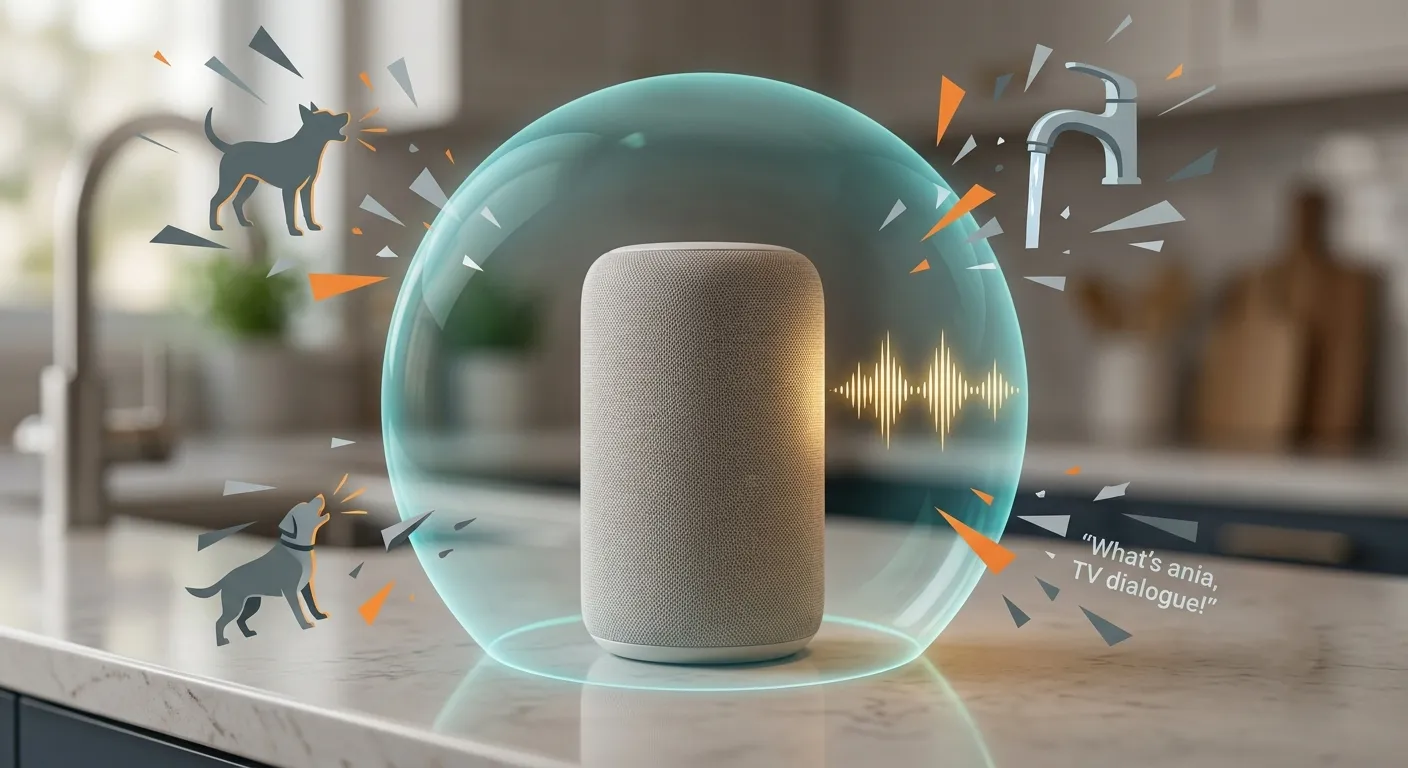
This is the layer most datasets underinvest in, and it is the one that controls false accepts. A wake word model learns what the phrase is partly by learning what it is not, which requires large volumes of ordinary speech, background media, and phonetically similar words and phrases that should never trigger the device. Without deliberate confusable sampling, a model will wake for near-misses, brand names that share syllables, or the radio ad from the opening scenario.
Voice Command Intent Coverage
Once the device is awake, the voice command dataset has to reflect how people actually phrase requests. Users rarely say the scripted version of a command, so the data needs natural variation in wording, partial phrases, hesitations, and code-switching, where speakers move between two languages within a single request. These four layers describe the target, but most data strategies fall short of it in predictable ways.
Where Common Wake Word Data Strategies Break Down
The standard approach to wake word collection still leans on scripted read speech recorded in quiet conditions by a small pool of contributors. It is fast and cheap, and it produces clean audio that trains well in the lab, but it teaches the model a version of the phrase that almost nobody uses once the product ships. The gap between that clean training audio and the noisy, accented, far-field reality of deployment is exactly where false rejects come from.
A second common shortcut is leaning on synthetic speech to fill coverage gaps. Text-to-speech voices and heavy augmentation have a place in expanding a dataset, but they reproduce the patterns of the systems that generated them rather than the variability of real speakers, so a model trained mostly on synthetic samples tends to perform well on synthetic tests and poorly on people. The same problem appears when teams treat volume as balance, collecting thousands of utterances from the same few hundred voices and assuming the size of the dataset will cover the diversity it lacks.
The final limitation is structural. Off-the-shelf data can support generic speech recognition, but it cannot exist for a phrase the brand invented last quarter, so a custom wake word always requires custom collection with its own quality design. If you are scoping that collection now, it helps to see what a structured wake words and voice commands dataset includes before writing your own specification. What that specification should prioritize also depends heavily on where the voice assistant will be used.
Voice Assistant Use Cases and the Data Each One Demands
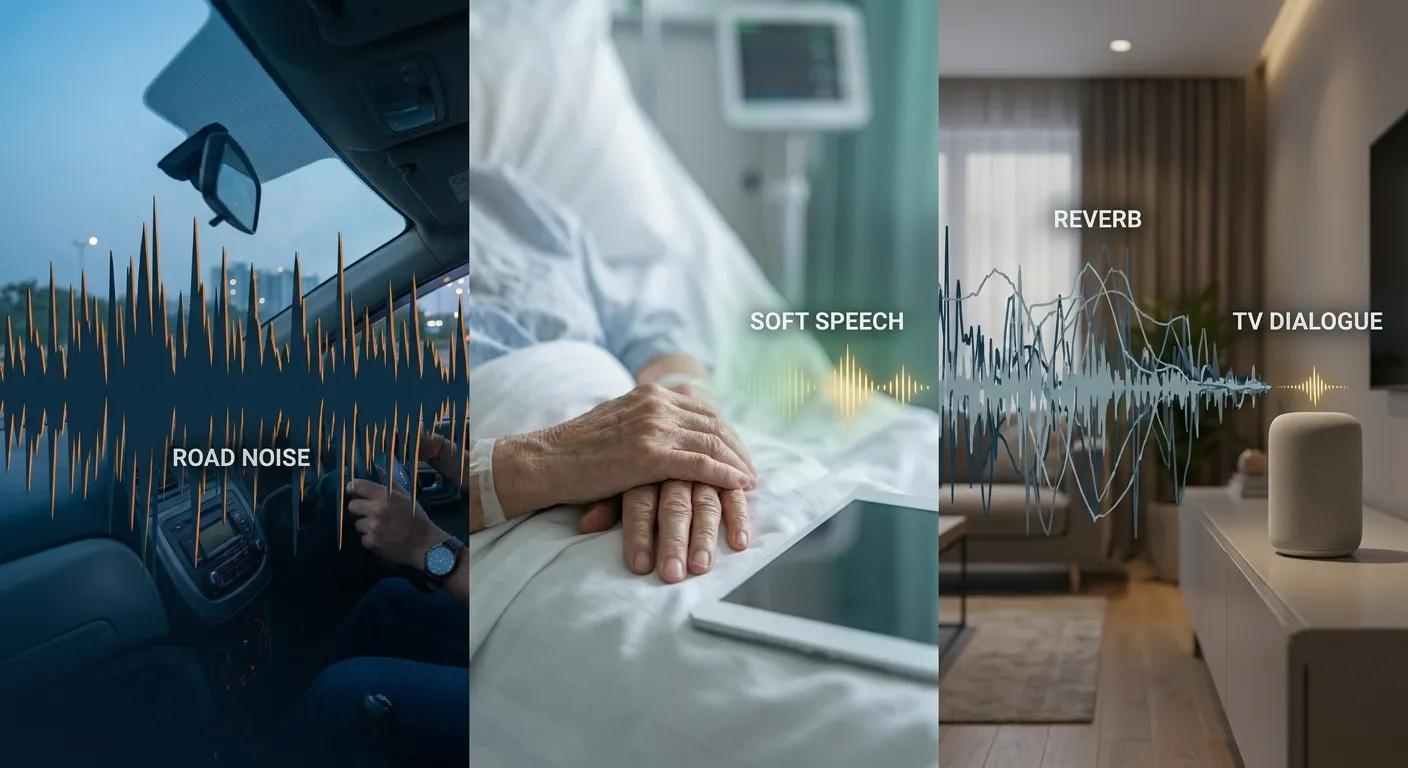
The four coverage layers apply everywhere, but their weight shifts by industry. A data plan that works for a smart speaker can fail in a car, and the reverse is just as true, so the use case should shape the collection specification from the first draft.
Automotive Voice Assistants: In-vehicle assistants handle navigation, calls, media, and vehicle settings while the driver keeps their hands on the wheel, which makes a missed wake word a safety issue as well as a usability one. The data has to capture engine and road noise at different speeds, open and closed windows, climate control fans, and multiple occupants speaking at once. It also needs speaker coverage for the regions the vehicle will be sold in, since a model tuned on one market's accents can underperform badly in the next.
Healthcare Voice Assistants: Healthcare assistants support appointment scheduling, medication reminders, and access to care information, and they are often used by older patients or people with reduced mobility. That shifts the speaker profile toward voices that general datasets underrepresent, including slower speech, softer volume, and age-related changes in articulation. Because these recordings sit close to regulated environments, consented collection and documented data handling matter as much as acoustic quality.
Retail and BFSI Voice Assistants: Retail and banking assistants handle order tracking, product queries, balance checks, and service requests through apps, kiosks, and contact channels. The acoustic conditions range from quiet homes to busy stores and branches, and the command vocabulary includes product names, account terms, and numbers that need accurate recognition. A false accept in a banking context is more than an annoyance, so negative and confusable sampling carries extra weight here.
Smart Home Voice Assistants: Smart home and IoTvoice assistants control lighting, thermostats, security systems, and appliances, almost always from across a room. Far-field recordings, reverberant spaces, and constant background media are the default conditions, and a television playing dialogue is one of the most common sources of false acceptance. Across all four use cases, the deciding factor is less the model than the partner who designs and collects the data, which is why evaluation deserves its own scrutiny.
How to Evaluate a Wake Word Data Partner
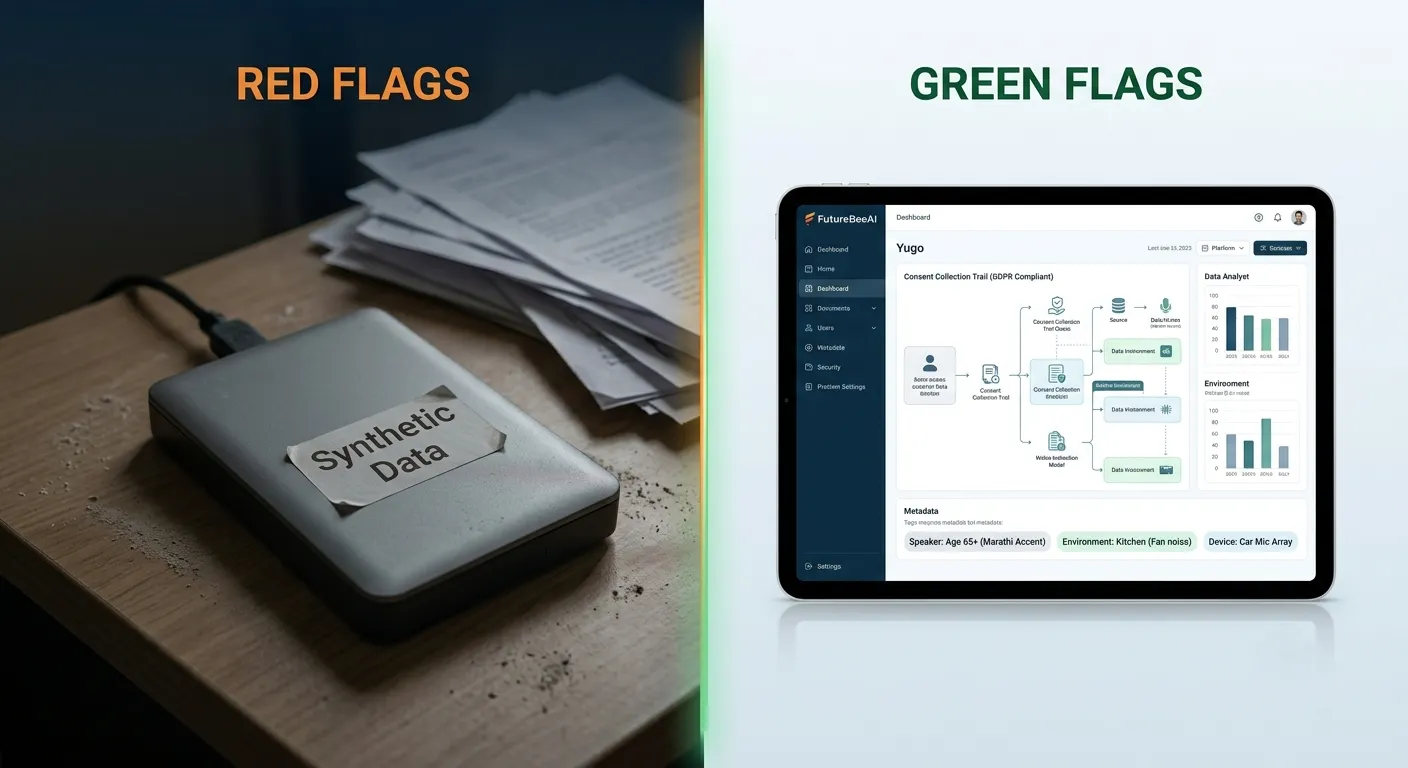
Most vendors can deliver a large number of recordings, so volume alone says very little about whether a dataset will hold up in production. The more useful signals sit in how the partner designs, sources, and checks the data, and they tend to surface in the first few scoping conversations.
Red flags to watch for:
Fixed collection templates: The vendor offers the same script and recording setup regardless of your device, market, or use case.
No negative data plan: Confusable phrases and background speech are treated as optional extras rather than core deliverables.
Unclear contributor consent: The vendor cannot explain how speakers were recruited, informed, and compensated.
Synthetic-heavy coverage: Diversity gaps are filled mainly with text-to-speech voices or augmentation.
Split accountability: Collection, annotation, and QA are handed between different subcontractors with no single owner.
Green flags to look for:
Collection designed around your product: Speaker mix, environments, and devices are specified from your deployment conditions.
Device and format control: Recordings can be captured on target device types, sample rates, and formats.
Consent as a quality mechanism: Informed, consented contributors produce more intentional and consistent recordings, and the consent trail supports GDPR, HIPAA, or DPDPA review where your use case needs it.
Metadata you can audit: Every file carries speaker, environment, and device metadata, so coverage can be verified rather than assumed.
One standard from collection to delivery: A single team owns the pipeline end to end, so quality expectations do not erode at handoffs.
This is the model FutureBeeAI works to: custom collection designed around the client's product and markets, recorded through its Yugo platform across mobile and web devices, with consented contributors and one accountable team from collection through delivery, because that continuity is what turns a wake word from a lab result into something users trust every day.
The Wake Word Is a Promise, and the Data Decides Whether It Is Kept
A wake word is the only part of a voice assistant that users say every single time, often dozens of times a day, which makes it the most repeated brand interaction a product has. When it works, nobody notices it and when it fails, users stop speaking to the product long before they file a complaint. The teams that get it right are rarely the ones with the most sophisticated model. They are the ones who treated the dataset as the product specification and designed it around the people, rooms and roads the device would actually meet.
If you are scoping a custom wake word or voice command dataset, talk to the FutureBeeAI team to map the collection plan to your devices, markets and use case. If you are still exploring requirements, browse FutureBeeAI's library of 2000+ datasets, starting with the wake words and voice commands dataset.
Frequently Asked Questions
Q. How much data does a custom wake word dataset need?
A. There is no fixed number, because the right size depends on the target markets, devices, and acceptable false accept rate. Speaker count and coverage balance matter more than raw utterance count, so plan the collection around how many distinct voices, accents, and environments the model must handle, then size the volume from there.
Q. What is the difference between wake word data and voice command data?
A. Wake word data trains a small always-on model to detect one specific phrase and ignore everything else. Voice command data trains the speech recognition and intent layers that interpret the request after the device wakes, so it needs far more variation in wording and vocabulary.
Q. Why does a wake word dataset need negative samples?
A. Negative samples teach the model what should not trigger it, including ordinary conversation, background media, and phonetically similar words. Without them, a model may detect the wake word reliably but also wake for near-misses, which drives up false acceptances.
Q. Can synthetic speech replace real recordings for wake word training?
A. Synthetic speech can supplement a dataset, but it should not replace real recordings. Text-to-speech voices lack the natural variability of real speakers across accents, ages, and environments, so models trained mainly on synthetic audio tend to underperform in real use.
A. Each recording should carry speaker attributes such as age group, gender, and accent or dialect, along with the recording environment, device type, sample rate, and distance from the microphone. This metadata is what allows teams to verify coverage and diagnose field failures by segment.
 14 November 2023

 Share this article on